flashinfer.sparse
Kernels for block sparse flashattention.
- class flashinfer.sparse.BlockSparseAttentionWrapper(float_workspace_buffer: Tensor, backend: str = 'auto')
Wrapper class for attention computation with a block-sparse matrix as attention mask. The definition of block sparse matrix can be found at bsr_matrix in SciPy.
This API supports any block size
(R, C).Example
>>> import torch
>>> import flashinfer
>>> num_qo_heads = 32
>>> num_kv_heads = 8
>>> head_dim = 128
>>> # allocate 128MB workspace buffer
>>> workspace_buffer = torch.empty(128 * 1024 * 1024, dtype=torch.uint8, device="cuda:0")
>>> bsr_wrapper = flashinfer.BlockSparseAttentionWrapper(workspace_buffer)
>>> # sparse mask: [[0, 0, 1], [1, 0, 1], [0, 1, 1]]
>>> M = 3
>>> N = 3
>>> indptr = torch.tensor([0, 1, 3, 5], dtype=torch.int32, device="cuda:0")
>>> indices = torch.tensor([2, 0, 2, 1, 2], dtype=torch.int32, device="cuda:0")
>>> bsr_wrapper.plan(
...     indptr,
...     indices,
...     M,
...     N,
...     1, # R(block_rows)=1
...     1, # C(block_columns)=1
...     num_qo_heads,
...     num_kv_heads,
...     head_dim,
... )
>>> q = torch.randn((M, num_qo_heads, head_dim), dtype=torch.float16, device="cuda:0")
>>> k = torch.randn((N, num_kv_heads, head_dim), dtype=torch.float16, device="cuda:0")
>>> v = torch.randn((N, num_kv_heads, head_dim), dtype=torch.float16, device="cuda:0")
>>> o = bsr_wrapper.run(q, k, v)
>>> # use dense implementation with attention mask for comparison
>>> mask = torch.tensor([[0, 0, 1], [1, 0, 1], [0, 1, 1]], dtype=torch.bool, device="cuda:0")
>>> o_ref = flashinfer.single_prefill_with_kv_cache(q, k, v, custom_mask=mask)
>>> torch.allclose(o, o_ref)
True
- __init__(float_workspace_buffer: Tensor, backend: str = 'auto') None
Construct a
BlockSparseAttentionWrapper.- Parameters:
float_workspace_buffer (torch.Tensor) – The user-reserved float workspace buffer used to store intermediate attention results in the split-k algorithm. The recommended size is 128MB, the device of the workspace buffer should be the same as the device of the input tensors.
backend (str) – The implementation backend can be
auto/fa2/fa3orcake. Defaults toauto. If set toauto, the function will automatically choose the backend based on the device architecture and kernel availability.
- plan(indptr: Tensor | None, indices: Tensor | None, M: int, N: int, R: int, C: int, num_qo_heads: int, num_kv_heads: int, head_dim: int, mask: Tensor | None = None, packed_mask: Tensor | None = None, causal: bool = False, pos_encoding_mode: str = 'NONE', use_fp16_qk_reduction: bool = False, logits_soft_cap: float | None = None, sm_scale: float | None = None, rope_scale: float | None = None, rope_theta: float | None = None, q_data_type: str | dtype = 'float16', kv_data_type: str | dtype | None = None, o_data_type: str | dtype = 'float16', non_blocking: bool = True, block_mask: Tensor | None = None, kv_block_lens: Tensor | None = None, q2k_indices: Tensor | None = None, q2k_num: Tensor | None = None, kv_splits: int | str | None = None, use_clc: bool | None = None, q_scale: Tensor | None = None, k_scale: Tensor | None = None, v_scale: Tensor | None = None) None
Create auxiliary data structures for block sparse attention.
- Parameters:
indptr (torch.Tensor, optional) – The block index pointer of the block-sparse matrix on row dimension, shape
(MB + 1,), whereMBis the number of blocks in the row dimension. Required for all backends exceptcake,vsa_sm100_blk128,vsa_sm100_blk64, andvsa_sm120_blk64whenblock_maskis provided.indices (torch.Tensor, optional) – The block indices of the block-sparse matrix on column dimension, shape
(nnz,), wherennzis the number of non-zero blocks. The elements in theindicesarray should be less thanNB: the number of blocks in the column dimension. Required for all backends exceptcake,vsa_sm100_blk128,vsa_sm100_blk64, andvsa_sm120_blk64whenblock_maskis provided.M (int) – The number of rows of the block-sparse matrix,
MB = ceil_div(M, R).N (int) – The number of columns of the block-sparse matrix,
NB = N // C,Nshould be divisible byC.R (int) – The number of rows in each block.
C (int) – The number of columns in each block.
num_qo_heads (int) – The number of heads in the query/output tensor.
num_kv_heads (int) – The number of heads in the key/value tensor.
head_dim (int) – The dimension of each head.
mask (torch.Tensor, optional) – The mask tensor with shape
(nnz, R, C,), where nnz is the number of non-zero blocks. If every block is full, then we don’t need to provide the mask tensor.packed_mask (torch.Tensor, optional) – The 1D packed mask tensor. If provided,
maskwill be ignored. The packed mask tensor is generated byflashinfer.quantization.packbits().causal (bool) – Whether to apply causal mask to the attention matrix. This is only effective when neither
masknorpacked_maskis provided inplan().pos_encoding_mode (str, optional) – The position encoding applied inside attention kernels, could be
NONE/ROPE_LLAMA(LLAMA style rotary embedding) /ALIBI. Default isNONE.use_fp16_qk_reduction (bool) – Whether to use f16 for qk reduction (faster at the cost of slight precision loss).
logits_soft_cap (Optional[float]) – The attention logits soft capping value (used in Gemini, Grok and Gemma-2, etc.), if not provided, will be set to
0. If greater than 0, the logits will be capped according to formula: \(\texttt{logits_soft_cap} \times \mathrm{tanh}(x / \texttt{logits_soft_cap})\), where \(x\) is the input logits.sm_scale (Optional[float]) – The scale used in softmax, if not provided, will be set to
1.0 / sqrt(head_dim).rope_scale (Optional[float]) – The scale used in RoPE interpolation, if not provided, will be set to
1.0.rope_theta (Optional[float]) – The theta used in RoPE, if not provided, will be set to
1e4.q_data_type (str, optional) – The data type of the query tensor.
kv_data_type (Optional[Union[str, torch.dtype]]) – The data type of the key/value tensor. If None, will be set to
q_data_type.o_data_type (str, optional) – The data type of the output tensor. Default is
half. Because it cannot be inferred from the input dtype during quantization, specify it explicitly.non_blocking (bool) – Whether to copy the input tensors to the device asynchronously, defaults to
True.block_mask (torch.Tensor, optional) – Per-head block-level attention mask, dtype bool. Shape may be either
(num_qo_heads, MB, NB)or(num_kv_heads, MB, NB).block_mask[h, i, j] = Truemeans the Q-blockiattends to KV-blockjfor headh. For GQA (num_qo_heads > num_kv_heads), when providing(num_qo_heads, MB, NB), the first QO-head from each KV-head group is used (sparsity must be the same across QO-heads that share a KV-head). Supported by thecake,vsa_sm100_blk128,vsa_sm100_blk64, andvsa_sm120_blk64backends. When provided,indptr/indicesare not required and will be ignored.kv_block_lens (torch.Tensor, optional) – Number of valid tokens in every KV block, shape
(NB,). Entries must be in[1, C]. Supported by thecakeblock-64 route; when omitted, every block is treated as havingCvalid tokens.q2k_indices (torch.Tensor, optional) – Direct per-head KV-block selections, contiguous int32 with shape
(num_qo_heads, MB, topk). Supported by thecakeblock-64 route and mutually exclusive withblock_maskand BSR metadata.q2k_num (torch.Tensor, optional) – Number of valid entries in each direct selection row, contiguous int32 with shape
(num_qo_heads, MB). When omitted, every direct row uses the fulltopkdimension.kv_splits (Optional[Union[int, str]]) – Number of KV splits for the split-KV combine path, or
"auto"to pick a split count from the sparsity heuristics. Only supported for thevsa_sm100_blk64backend; must beNonefor all other backends.None(default) disables splitting, equivalent to passing1explicitly. Pass"auto"to select the split count automatically via a sparsity heuristic.use_clc (Optional[bool]) – Override the SM100 blk64 scheduler:
Trueforces the CLC persistent scheduler,Falseforces the static scheduler,None(default) uses the shape-based heuristic. Only supported for thevsa_sm100_blk64backend.q_scale (torch.Tensor, optional) – Sage FP8 quantization scale for
q, shape(1, num_qo_heads, seqlen_q), float32. Only supported for thevsa_sm100_blk64backend, and only whenq/k/varefloat8_e4m3fn. Must be provided together withk_scale/v_scale, or not at all. The Sage FP8 path additionally requiresbatch_size == 1,num_qo_heads in (4, 8), and dense (non-variable) block sparsity – seebsa_attn_sm100_blk64_fwd().k_scale (torch.Tensor, optional) – Sage FP8 quantization scale for
k, shape(1, num_qo_heads, ceil(seqlen_k / 16)), float32. Seeq_scale.v_scale (torch.Tensor, optional) – Sage FP8 quantization scale for
v, shape(num_qo_heads, head_dim), float32. Seeq_scale.
Notes
The
plan()method should be called before anyrun()orrun_return_lse()calls, auxiliary data structures will be created during this call and cached for multiple kernel runs.The
num_qo_headsmust be a multiple ofnum_kv_heads. Ifnum_qo_headsis not equal tonum_kv_heads, the function will use grouped query attention.Note
The
vsa_sm100_blk64backend does not support GQA/MQA: it has no KV-head mapping and requiresnum_kv_heads == num_qo_heads.
- reset_workspace_buffer(float_workspace_buffer: Tensor, int_workspace_buffer: Tensor) None
Reset the workspace buffer.
- Parameters:
float_workspace_buffer (torch.Tensor) – The new float workspace buffer, the device of the new float workspace buffer should be the same as the device of the input tensors.
int_workspace_buffer (torch.Tensor) – The new int workspace buffer, the device of the new int workspace buffer should be the same as the device of the input tensors.
- run(q: Tensor, k: Tensor, v: Tensor, scale_q: Tensor | None = None, scale_k: Tensor | None = None, scale_v: Tensor | None = None, out: Tensor | None = None, lse: Tensor | None = None, return_lse: bool = False, enable_pdl: bool | None = None) Tensor | Tuple[Tensor, Tensor]
Compute block-sparse attention between Q/K/V tensors.
- Parameters:
q (torch.Tensor) – The query tensor with shape
(M, num_qo_heads, head_dim).k (torch.Tensor) – The key tensor with shape
(N, num_kv_heads, head_dim).v (torch.Tensor) – The value tensor with shape
(N, num_kv_heads, head_dim).scale_q (Optional[torch.Tensor]) – The scale tensor for query, per-head quantization with shape:
[num_qo_heads]. Used with FP8 Quantization. If not provided, will be set to1.0.scale_k (Optional[torch.Tensor]) – The scale tensor for key, per-head quantization with shape:
[num_kv_heads]. Used with FP8 Quantization. If not provided, will be set to1.0.scale_v (Optional[torch.Tensor]) – The scale tensor for value, per-head quantization with shape:
[num_kv_heads]. Used with FP8 Quantization. If not provided, will be set to1.0.out (Optional[torch.Tensor]) – The output tensor, if not provided, will be allocated internally.
lse (Optional[torch.Tensor]) – The log-sum-exp of attention logits, if not provided, will be allocated internally.
return_lse (bool) – Whether to return the log-sum-exp of attention logits
enable_pdl (bool) – Whether to enable Programmatic Dependent Launch (PDL). See https://docs.nvidia.com/cuda/cuda-programming-guide/04-special-topics/programmatic-dependent-launch.html Only supported for >= sm90, and currently only for FA2 and CUDA core decode.
- Returns:
If
return_lseisFalse, the attention output, shape:[M, num_qo_heads, head_dim]. Ifreturn_lseisTrue, a tuple of two tensors:The attention output, shape:
[M, num_qo_heads, head_dim].The logsumexp of attention output, shape:
[M, num_qo_heads].
- Return type:
Union[torch.Tensor, Tuple[torch.Tensor, torch.Tensor]]
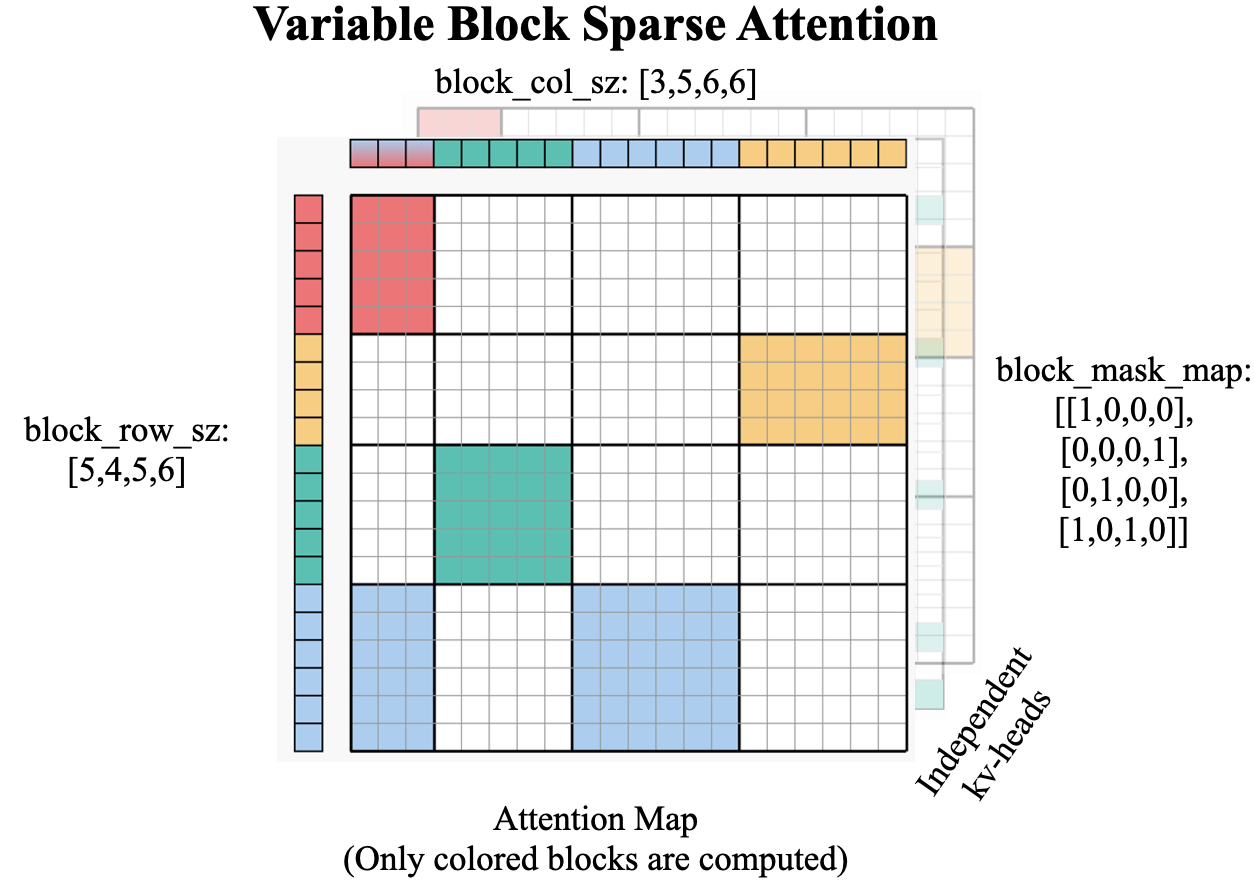
- class flashinfer.sparse.VariableBlockSparseAttentionWrapper(float_workspace_buffer: Tensor, backend: str = 'auto')
Wrapper class for attention computation with a block-sparse matrix as attention mask. This API supports variable block sizes provided by
block_row_szandblock_col_sz. Besides, eachkv_head_idxcan specify its own sparse patterns without using the same mask.Example
>>> import torch
>>> import flashinfer
>>> num_qo_heads = 1
>>> num_kv_heads = 1
>>> head_dim = 128
>>> seq_len = 6 # This corresponds to the `block_row_sz` and `block_col_sz`
>>> # allocate 128MB workspace buffer
>>> workspace_buffer = torch.empty(128 * 1024 * 1024, dtype=torch.uint8, device="cuda:0")
>>> wrapper = flashinfer.VariableBlockSparseAttentionWrapper(workspace_buffer)
>>> block_mask_map = torch.tensor([[[0, 0, 1], [1, 0, 1], [0, 1, 1]]], dtype=torch.bool, device="cuda:0")
>>> block_row_sz = torch.tensor([[1, 2, 3]], dtype=torch.int32, device="cuda:0")
>>> block_col_sz = torch.tensor([[3, 1, 2]], dtype=torch.int32, device="cuda:0")
>>> wrapper.plan(
...     block_mask_map,
...     block_row_sz,
...     block_col_sz,
...     num_qo_heads,
...     num_kv_heads,
...     head_dim,
... )
>>> q = torch.randn((num_qo_heads, seq_len, head_dim), dtype=torch.float16, device="cuda:0")
>>> k = torch.randn((num_kv_heads, seq_len, head_dim), dtype=torch.float16, device="cuda:0")
>>> v = torch.randn((num_kv_heads, seq_len, head_dim), dtype=torch.float16, device="cuda:0")
>>> o = wrapper.run(q, k, v)
- __init__(float_workspace_buffer: Tensor, backend: str = 'auto') None
Construct a
VariableBlockSparseAttentionWrapper.- Parameters:
float_workspace_buffer (torch.Tensor) – The user-reserved float workspace buffer used to store intermediate attention results in the split-k algorithm. The recommended size is 128MB, the device of the workspace buffer should be the same as the device of the input tensors.
backend (str) – The implementation backend, could be
auto/fa2/fa3or the explicitcake(generated Cake kernels; Hopper SM90 only: BF16 HND or Sage FP8float8_e4m3fnHND withq_scale/k_scale/v_scalegiven toplan(), head_dim 128,num_qo_heads = g x num_kv_headswithgin {1, 2, 4, 8} (g > 1: grouped-query attention on the kv-head-shaped block mask,k/vand their scales per kv head; other ratios raiseValueError), noncausal 64-token blocks, 1..64 selected KV blocks per query block; small selections (at most 6 blocks per query block and a grid that fits one wave) route to a one-CTA-per-query-block kernel with the plan passed in the kernel parameter bank, everything else to the persistent kernel; the FP8 and GQA kernels are twins of the BF16 MHA ones on their plans).cake_cuteis accepted as an alias ofcake(the name of its former CuTe DSL build). Defaults toauto. Automatic selection never selectscake. If set toauto, the function will automatically choose the backend based on the device architecture and kernel availability.
- plan(block_mask_map: Tensor, block_row_sz: Tensor, block_col_sz: Tensor, num_qo_heads: int, num_kv_heads: int, head_dim: int, causal: bool = False, pos_encoding_mode: str = 'NONE', use_fp16_qk_reduction: bool = False, logits_soft_cap: float | None = None, sm_scale: float | None = None, rope_scale: float | None = None, rope_theta: float | None = None, non_blocking: bool = True, q_data_type: str | dtype = 'float16', kv_data_type: str | dtype | None = None, q_scale: Tensor | None = None, k_scale: Tensor | None = None, v_scale: Tensor | None = None) None
Create auxiliary data structures for block sparse attention.
- Parameters:
block_mask_map (torch.Tensor) – The block mask map (boolean), shape
(num_kv_heads, MB, NB), whereMBis the number of blocks in the row dimension,NBis the number of blocks in the column dimension.block_row_sz (torch.Tensor) – The block row size, shape
(num_kv_heads, MB,).block_col_sz (torch.Tensor) – The block column size, shape
(num_kv_heads, NB,).num_qo_heads (int) – The number of heads in the query/output tensor.
num_kv_heads (int) – The number of heads in the key/value tensor. Note that a group of
qo_headsshares the same sparse pattern ofkv_heads.head_dim (int) – The dimension of each head.
causal (bool) – Whether to apply causal mask to the attention matrix.
pos_encoding_mode (str, optional) – The position encoding applied inside attention kernels, could be
NONE/ROPE_LLAMA(LLAMA style rotary embedding) /ALIBI. Default isNONE.use_fp16_qk_reduction (bool) – Whether to use f16 for qk reduction (faster at the cost of slight precision loss).
logits_soft_cap (Optional[float]) – The attention logits soft capping value (used in Gemini, Grok and Gemma-2, etc.), if not provided, will be set to
0. If greater than 0, the logits will be capped according to formula: \(\texttt{logits_soft_cap} \times \mathrm{tanh}(x / \texttt{logits_soft_cap})\), where \(x\) is the input logits.sm_scale (Optional[float]) – The scale used in softmax, if not provided, will be set to
1.0 / sqrt(head_dim).rope_scale (Optional[float]) – The scale used in RoPE interpolation, if not provided, will be set to
1.0.rope_theta (Optional[float]) – The theta used in RoPE, if not provided, will be set to
1e4.non_blocking (bool) – Whether to copy the input tensors to the device asynchronously, defaults to
True.q_data_type (Union[str, torch.dtype]) – Dtype of the query tensor. Used to specialize the JIT-compiled kernel. Defaults to
"float16". Forbackend="cake",torch.float8_e4m3fnselects the Sage FP8 kernels and requires the three scales below.kv_data_type (Optional[Union[str, torch.dtype]]) – Dtype of the key/value tensors. When
None, defaults toq_data_type.q_scale (Optional[torch.Tensor]) –
backend="cake"Sage FP8 only: per-token FP32 query scales, shape(1, num_qo_heads, MB * 64), contiguous on the wrapper’s device.k_scale (Optional[torch.Tensor]) –
backend="cake"Sage FP8 only: per-16-token FP32 key scales, shape(1, num_kv_heads, ceil(NB * 64 / 16)).v_scale (Optional[torch.Tensor]) –
backend="cake"Sage FP8 only: per-channel FP32 value scales, shape(num_kv_heads, head_dim). The three scales are given together withq_data_type=torch.float8_e4m3fnor not at all; they are bound by the plan and read by everyrun()(a caller that re-quantizes per forward writes the same tensors in place), andrun()takes E4M3q/k/vand returns BF16.flashinfer.cake_vsa_sm90.sage_fp8_quantize_sm90()produces the four from BF16 HND tensors (k/vwithnum_kv_headsheads).backend="cake"acceptsnum_qo_heads = g x num_kv_headswithgin {1, 2, 4, 8}: the block mask and the K/V scales are shaped by the kv heads (above),q/q_scaleand the output by the query heads, and query headhattends kv headh // g; another ratio raisesValueErrorand anum_qo_headsthat is not a multiple ofnum_kv_headsis rejected as for every backend.
The
plan()method should be called before anyrun()orrun_return_lse()calls, auxiliary data structures will be created during this call and cached for multiple kernel runs.The
num_qo_headsmust be a multiple ofnum_kv_heads. Ifnum_qo_headsis not equal tonum_kv_heads, the function will use grouped query attention.
- reset_workspace_buffer(float_workspace_buffer: Tensor, int_workspace_buffer: Tensor) None
Reset the workspace buffer.
- Parameters:
float_workspace_buffer (torch.Tensor) – The new float workspace buffer, the device of the new float workspace buffer should be the same as the device of the input tensors.
int_workspace_buffer (torch.Tensor) – The new int workspace buffer, the device of the new int workspace buffer should be the same as the device of the input tensors.
- run(q: Tensor, k: Tensor, v: Tensor, out: Tensor | None = None, lse: Tensor | None = None, return_lse: bool = False, enable_pdl: bool | None = None) Tensor | Tuple[Tensor, Tensor]
Compute block-sparse attention between Q/K/V tensors.
- Parameters:
q (torch.Tensor) – The query tensor with shape
(num_qo_heads, qo_len, head_dim).k (torch.Tensor) – The key tensor with shape
(num_kv_heads, kv_len, head_dim).v (torch.Tensor) – The value tensor with shape
(num_kv_heads, kv_len, head_dim).out (Optional[torch.Tensor]) – The output tensor, if not provided, will be allocated internally.
lse (Optional[torch.Tensor]) – The log-sum-exp of attention logits, if not provided, will be allocated internally.
return_lse (bool) – Whether to return the log-sum-exp of attention logits
enable_pdl (bool) – Whether to enable Programmatic Dependent Launch (PDL). See https://docs.nvidia.com/cuda/cuda-programming-guide/04-special-topics/programmatic-dependent-launch.html Only supported for >= sm90, and currently only for FA2 and CUDA core decode.
- Returns:
If
return_lseisFalse, the attention output, shape:[num_qo_heads, qo_len, head_dim]. Ifreturn_lseisTrue, a tuple of two tensors:The attention output, shape:
[num_qo_heads, qo_len, head_dim].The logsumexp of the attention logits, shape:
[num_qo_heads, qo_len].
For
backend="cake"the output follows the same DPS ABI (outis[H*M, 1, head_dim]) and the return value is the HND view[H, M, head_dim];outmust be contiguous and must not overlapq/k/v. A Sage FP8 plan takesfloat8_e4m3fnq/k/v(the scales were bound byplan()) and writes BF16.- Return type:
Union[torch.Tensor, Tuple[torch.Tensor, torch.Tensor]]
Cake VSA
|
Create stable metadata and workspaces for the source-level backend. |
|
Run one explicit source-level route; no external fallback is available. |
Token-Sparse Attention Inputs
Build cache-slot lists for token-sparse attention. Build grouped key unions and masks for masked dense attention.
|
Build the K/V slot lists of token-sparse attention from key positions. |
|
Build the inputs of masked dense attention from key positions: each group of consecutive tokens' union of keys, and each token's bitmask over it. |
|
The most keys |
SDSA Indexer
Score, select and quantize the keys of the SDSA (Simplified DSA) indexer, which has one query head and no head weights.
|
Compute FP32 scores of query rows against their request's paged keys. |
|
Select the keys that score above each query row's threshold, in one pass over the row's paged keys and without writing its scores. |
|
Write each query row's exact Top-K keys from the candidates and ties that |
|
Copy a strided random sample of each request's paged keys into dense sample rows, whose scores give thresholds for |
|
Set each query row's threshold for |
|
Quantize indexer keys and queries to NVFP4 in one launch: the keys into a paged key cache and the queries into rows, the layouts |
flashinfer.msa_ops
Minimax Sparse Attention (MSA) sparse prefill, sparse decode, and top-k
selection dispatch on SM100/SM103/SM107/SM120/SM121. msa_proxy_score also
supports SM90; only msa_proxy_score_fp4 is SM120/SM121-only. On
SM100/SM103/SM107, packed NVFP4 K/V is served by dedicated
paged-KV prefill and decode routes that take the four regions of a packed
NVFP4 page – K data, K scales, V data, V scales – as strided views of one
allocation, for the MiniMax-M3 head geometry (head dimension 128, page size
128, and 64/4, 32/2 or 16/1 query/KV heads per tensor-parallel rank);
msa_prefill_nvfp4_specialized_stats() and
msa_decode_nvfp4_specialized_stats() report the exact accepted set. Other
NVFP4 forms – flat or ragged K/V, or separately allocated scale tensors –
remain SM120/SM121-only, and outside those routes the 10.0/10.3/10.7 backend
requires separate contiguous K and V tensors and does not make implicit
copies. The decode out= parameter is implemented by that 10.0/10.3/10.7 route
alone; every other route raises NotImplementedError when it is passed.
The compute capability 10.0/10.3/10.7 backend uses TopK16 as its generic contract;
non-TopK16 shapes fail closed instead of entering a generic kernel. The decode
path uses direct persistent M16 ownership for both Q1 and multi-token decode;
it does not route BF16 decode through prefill or split-K. With
force_fused=True, two frozen BF16-query/FP8-KV single-query serving shapes
use transformed direct kernels, and paged uniform FP8 Q/K/V supports Q1
through Q32 and returns BF16 output. Long BF16 causal prefill uses a
selected-block reverse producer and deterministic reduction when every
request of the call has at least 8192 queries (and, on flat K/V, at least
8192 keys).
The NVFP4 paged-KV prefill route on compute capability 10.0/10.3/10.7 requires
CUDA 13.0 or newer; on an older toolkit it declines with the reason, which
msa_prefill_nvfp4_specialized_stats() also reports as
toolkit_decline_reason. The decode route has no such floor. The generated
sm_107a decode programs of the cake backend additionally require an nvcc
that lists compute_107a; on a toolkit without it the backend reports no
generated program for a 10.7 device and its JIT declines those programs with
the reason instead of failing inside the build. The prefill
route is bitwise
reproducible run to run up to a 16,384-token context, and is not guaranteed to
be above it. The per-tile block union is consumed in ascending hash-slot order;
at or below 128 blocks per request the slot is a permutation of the selected
set, so no two selected ids collide, the insert is a commutative atomicOr
and repeated calls return identical bits. Above that width the insert falls
back to linear probing under atomicCAS, colliding ids land in whatever
order the atomics resolve in, and the accumulation order – and so the last
bits of the output – may differ between runs. Every result is correct either
way. msa_prefill_nvfp4_specialized_stats() reports the bound as
run_to_run_bitwise_reproducible_up_to_context.
Call flashinfer.msa_ops.supports_packed_kv() with the active device when
integrating a cache manager across these architectures; the legacy aggregate
SUPPORTS_PACKED_KV flag describes the SM120/SM121 backend.
Per-token tensor num_valid_pages for
flashinfer.msa_ops.msa_topk_select() is likewise SM120/SM121-only;
compute capability 10.0/10.3/10.7 requires a scalar value or None and rejects
the tensor form before backend dispatch.
CUDA graph capture of sparse prefill or decode on compute capability
10.0/10.3/10.7 requires a caller-owned
flashinfer.msa_ops.MSASparseAttentionWorkspace. Warm the workspace
eagerly with the exact tensors, options, and capture stream before capture.
The two FP8-KV single-query decode specializations are eager-only; under
capture the same inputs take the generic decode route.
|
MSA dense proxy pass for SM90 and SM120/SM121: per-KV-block max attention logits. |
|
NVFP4 MSA dense proxy pass for SM120/SM121 (the FP4 counterpart of |
|
Caller-owned storage for MSA CUDA graph capture on SM100/SM103 and SM107's packed-NVFP4 paged-KV routes. |
|
Return whether MSA accepts packed paged K/V views on |
|
Minimax Sparse Attention forward for SM90, SM100/SM103, SM107 (packed-NVFP4 paged K/V only), and SM120/SM121 GPUs. |
|
Sparse decode attention for SM100/SM103/SM107 and SM120/SM121 GPUs. |
|
Select the top-K KV blocks per query token based on attention scores. |
|
MiniMax-M3 ICP indexer
Experimental per-rank kernels of the MiniMax-M3 index-context-parallel (ICP)
indexer on compute capability 10.0, 10.3 and 10.7 (exact sm_100a,
sm_103a and sm_107a builds). The index keys are sharded by context across
a TP2 or TP4 group (P128 pages: rows interleaved across ranks; P256 pages:
contiguous 128-row halves for TP2, 64-row quarters for TP4), and every rank
holds the FP8 queries of all four index heads. Scores are raw FP32 q . k
maxima per logical 128-token block (B128); selection ranks them descending,
puts the forced begin/end blocks first and breaks exact ties toward the lower
block id. The entry points follow the MSA sharded-indexer contract: a device
plan and a chunked prefill scorer, a prefill Top16 selector into carrier rows,
a decode scorer, a decode Top16 selector that publishes into the owner ranks’
receive rows, and the owner-side merge. The caller owns every buffer and the
collective steps (receive-storage rendezvous, the prefill all-to-all); the
kernels never allocate or synchronize with the host and are CUDA Graph safe.
The receive storage is laid out by msa_icp_comm_layout; zero it and its
counters once and never reset them. Generation-tagged receive rows need at
least two sparse layers between uses of one slot set. Version 1 supports four
index heads.
The default decode chain is the score plane
(msa_icp_decode_index_score_sharded) followed by
msa_icp_topk_select_publish; msa_icp_decode_score_publish fuses the two
steps and is an option. The plan’s decode runs the fused chain when given a
pool, and without one on compute capability 10.7 at P128 (TP2 and TP4) from 8 requests
on, in a pool the plan allocates once (fused_decode_min_batch). With
enable_pdl on compute capability 10.0 and 10.3 at 64 or 128 local K rows per
page, the score plane, and on 10.7 at 32 or 64, both the score plane and the
fused chain’s list scorer, read seq_lens and block_table and start
loading the history index-K pages before they wait on the preceding kernel;
that kernel must not write them and must be launched
without programmatic dependent launch or wait on its own predecessor before it
triggers (enable_pdl=False removes this requirement). Call warmup() on
the plan returned by prepare_msa_icp_indexer on every rank before the first
exchange and before CUDA Graph capture: it loads every kernel into the device’s
context, so that no first launch waits on module loading while a peer’s merge
spins.
msa_icp_prefill_score_select fuses the prefill score and local Top16 steps
of one query window: a list scorer keeps per-work-item Top16 lists in a
caller-owned uint8 pool (msa_icp_prefill_pool_bytes) and a list merger
writes the same carrier rows as msa_icp_index_score_sharded followed by
msa_icp_topk_select_prefill, without the score scratch. The plan’s
prefill_local runs it when given a pool; prefill_pool_shape() and
prefill_window_tokens() size the pool for windows of at most
min(8192, max_num_batched_tokens) tokens. fused_prefill on the plan is
the serving default per layout (cake_backend.FUSED_PREFILL); it is False
on every layout in this version, so the fused path runs only on request.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
Sizes of a prefill plan's storage: |
|
Prefill score columns: |
|
Decode score columns: |
|
Bytes of the fused decode path's |
|
Bytes of the fused prefill path's |
|
Layout of the caller's decode receive storage. |